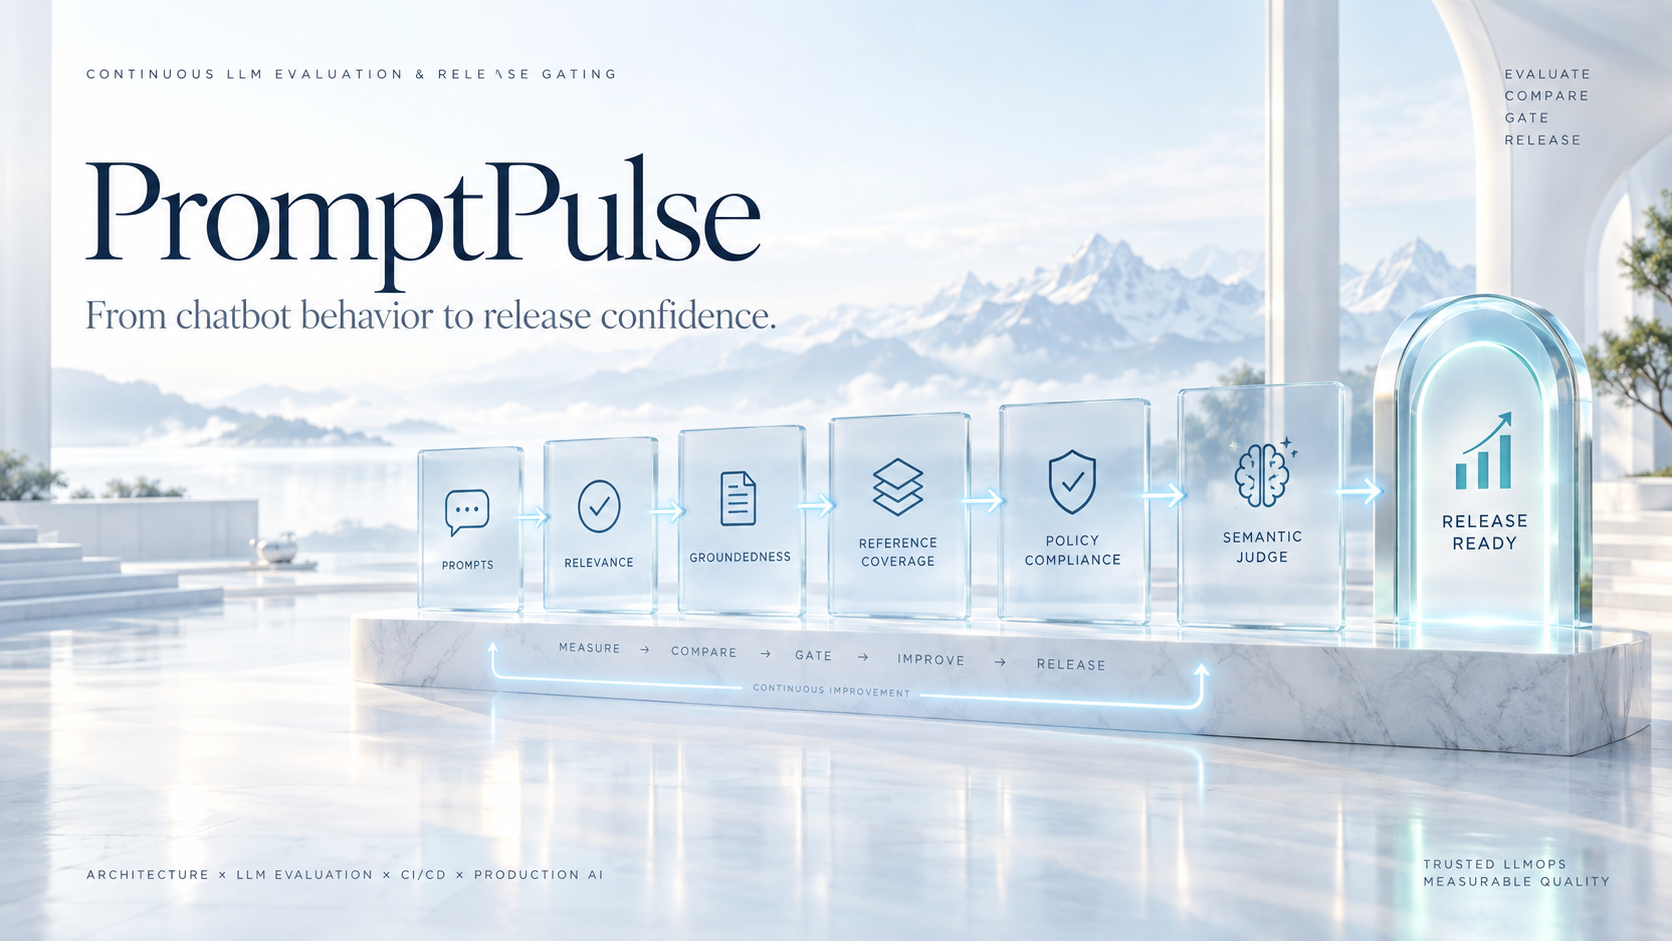
Continuous LLM Evaluation & Release Gating
Production-oriented LLM quality pipeline that turns chatbot behavior into repeatable release gates across relevance, groundedness, reference coverage and policy compliance.
Live Demo ↗ · Architecture · Quality Gates · CI/CD



Traditional unit tests verify deterministic software. LLM applications also need behavioral tests: after a prompt, model, retrieval, or application change, does the system remain relevant, grounded, policy-compliant, and complete enough for release?
PromptPulse turns those questions into a repeatable engineering loop:
Measure → Compare → Gate → Improve → Release
The project combines dataset-driven evaluation, live Hugging Face inference, fast deterministic gates, optional DeepEval semantic judging, GitHub Actions, and a Streamlit evaluation dashboard.
flowchart LR
    A[Prompt / Model / Dataset Change] --> B[Versioned Evaluation Cases]
    B --> C[Candidate Generation]
    C --> D[Deterministic Metrics]
    C --> E[Optional Semantic Judge]
    D --> F{Release Gate}
    E --> F
    F -->|pass| G[Release Ready]
    F -->|fail| H[Block Regression]
    G --> I[Production / Live Demo]
    I --> J[New Failure Evidence]
    J --> B
| Metric | Purpose | Release signal |
|---|---|---|
| Answer relevance | response addresses the user query | regression indicator |
| Groundedness | response stays within approved context | critical quality signal |
| Reference coverage | required source information is represented | completeness signal |
| Policy compliance | required terms present, prohibited terms absent | deterministic blocker |
| Pulse score | weighted aggregate | overall comparison signal |
| DeepEval judge | optional semantic evaluation | supporting evidence |
The deterministic checks remain transparent and reproducible. Semantic judging is supplemental rather than unquestioned release authority.
- Select a versioned scenario.
- Load the user query, approved reference context, and expected behavior.
- Generate a response with the configured Hugging Face model.
- Calculate deterministic quality metrics.
- Optionally run DeepEval when judge credentials are available.
- Apply the release threshold.
- Preserve failure evidence as the basis for the next regression case.
The Streamlit application is designed around evaluation rather than a generic chatbot UI. A reviewer can:
- choose an evaluation scenario;
- inspect approved reference context;
- select a Hugging Face model and generation settings;
- run live inference;
- inspect relevance, groundedness, reference coverage, policy compliance and Pulse score; and
- review the raw model response and reasons behind the score.
If HF_TOKEN is absent, deterministic demo responses keep the evaluation interface explorable without exposing credentials.
Fast checks run in CI without a paid judge API. These include relevance, grounding, reference coverage, required/forbidden term rules and the aggregate Pulse score.
When OPENAI_API_KEY is configured, DeepEval can add semantic metrics such as answer relevancy and hallucination checks against trusted context.
The semantic layer is optional by design: CI remains reproducible even when external judge credentials are unavailable.
.github/workflows/ai_evals.yml runs evaluation on pushes and pull requests:
- install pinned dependencies;
- validate the evaluation dataset;
- run deterministic quality gates;
- run optional DeepEval tests when configured;
- validate application imports; and
- publish test artifacts.
A failed quality gate blocks the regression from being treated as release-ready.
Scenarios live in tests/test_dataset.json, allowing new regression cases without changing evaluation code.
Each record can contain:
- scenario ID;
- user query;
- approved reference context;
- expected answer;
- required terms; and
- forbidden terms.
This makes evaluation assets versionable alongside the application code.
- no tokens are committed to the repository;
- secrets are read from environment variables or Streamlit secrets;
- local secrets are gitignored;
- token values are never printed;
- runtime inference and CI deployment can use separate least-privilege credentials.
git clone https://github.com/h00w/PromptPulse.git
cd PromptPulse
python -m venv .venv
pip install -r requirements-dev.txt
python -m pytest -q
streamlit run app/app.py
For live Hugging Face inference:
export HF_TOKEN="your_token"
streamlit run app/app.pyNatural extensions include:
- multi-turn benchmark cases;
- prompt/model baseline-vs-candidate comparison;
- latency and cost budgets;
- RAG faithfulness checks;
- historical run storage;
- PR annotations for failed scenarios;
- production trace ingestion; and
- observability integration.
Dataset → Inference → Deterministic Evaluation → Semantic Evidence → CI Gate → Live Dashboard → Regression Learning
- Live demo: https://prompt-pulse.streamlit.app/
- GitHub Actions: https://github.com/h00w/PromptPulse/actions/workflows/ai_evals.yml
- Evaluation source:
tests/test_dataset.json - Evaluation engine:
promptpulse/evaluation.py
Hendarmawan, PhD Eng.
LLMOps · AI Evaluation · Production AI · Release Engineering · AI Governance
MIT