Developed By ParagBML Access the original repository on Github : [(https://github.com/paragbml/Reinforcement-Learning-CMD-interface)] Email for any issues : parag@null.net
This is an implementation of the AlphaZero algorithm for playing Gomoku (also called Gobang or Five in a Row) from pure self-play training. The game Gomoku is much simpler than Go or chess, so that we can focus on the training scheme and obtain a AI model on a single PC in a few hours.
- Each move with 400 Monte Carlo tree search algorithm playouts:
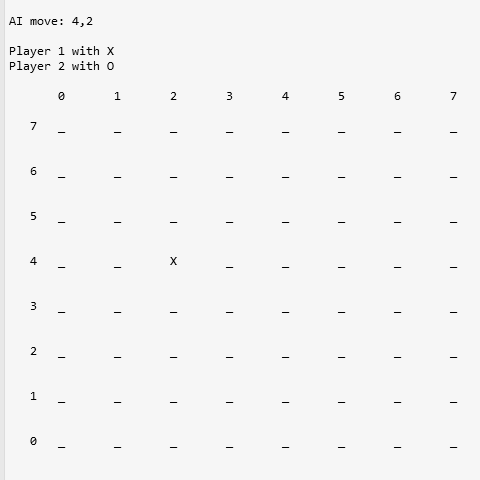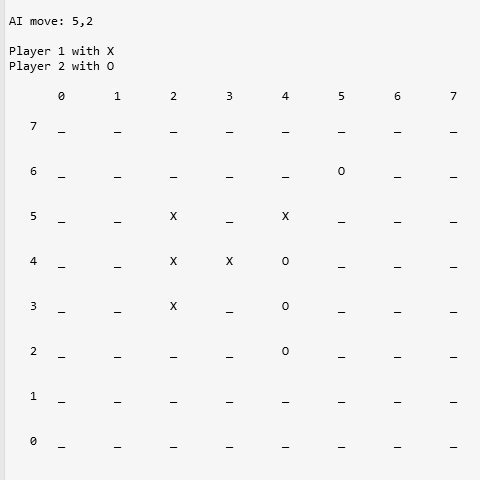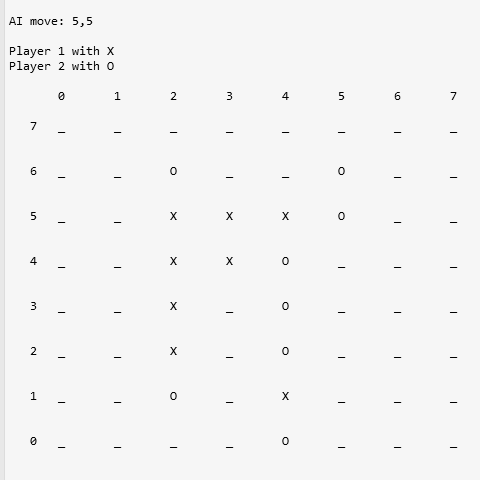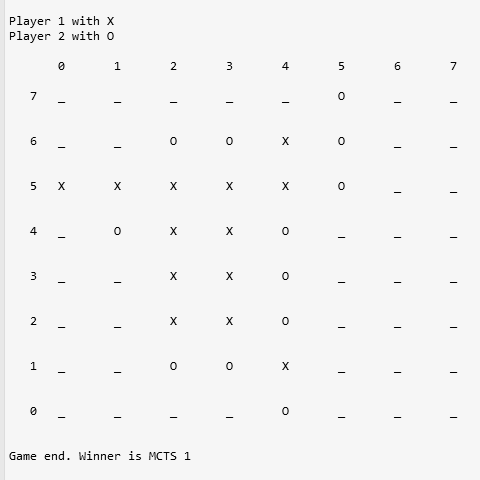
REQ
- Python >= 2.7
- Numpy >= 1.11
python human_play.py
python train.py
With PyTorch or TensorFlow, modify the file [train.py]
from policy_value_net import PolicyValueNet # Theano and Lasagne
and execute: python train.py
The models (best_policy.model and current_policy.model) will be saved every a few updates (default 50).